Fix high swap usage on Proxmox without buying RAM
High swap on Proxmox often means your guests were given too much memory. Measure what they use and fix it.
Before you start
- A Proxmox VE 8 or 9 host that you can reach over SSH as root.
- Permission to shut down or restart at least one guest.
- No paid subscription. Nothing here needs the subscription repository.
The example host has 16 threads, 62 GiB of RAM and about twenty guests. The steps work on any size.
Your values
Fill these in and every command below updates to match. Nothing is sent anywhere.
Run this at your own risk. These steps worked on my hardware; yours may differ. Take a backup first, read each command before running it, and see the disclaimer.
Swap is at 98 percent. The web interface is slow, and consoles freeze for a moment before they react. Your first thought is to buy more RAM. Usually you do not need to.
The real problem: your guests were given more memory than the host has. One of my hosts gave 123 GiB to its guests but had only 62 GiB installed, about twice as much. This works until the guests use a lot of it at the same time. Then the host moves memory to disk, and everything slows down.
This guide shows you how to measure the problem instead of guessing, and how to fix it by giving memory back. You do not need new hardware or a reinstall.
Confirm it is really swap, and not something else
free -h
swapon --show total used free shared buff/cache available
Mem: 62Gi 58Gi 1.2Gi 104Mi 3.4Gi 2.1Gi
Swap: 8.0Gi 7.8Gi 196MiLook at two numbers. If swap used is close to the total, the host has been moving memory to disk for some time. Available shows how much memory new programs can really get. Do not trust "free": it ignores cache that the system can clear. On a 62 GiB host, available memory below a few hundred MiB is the problem.
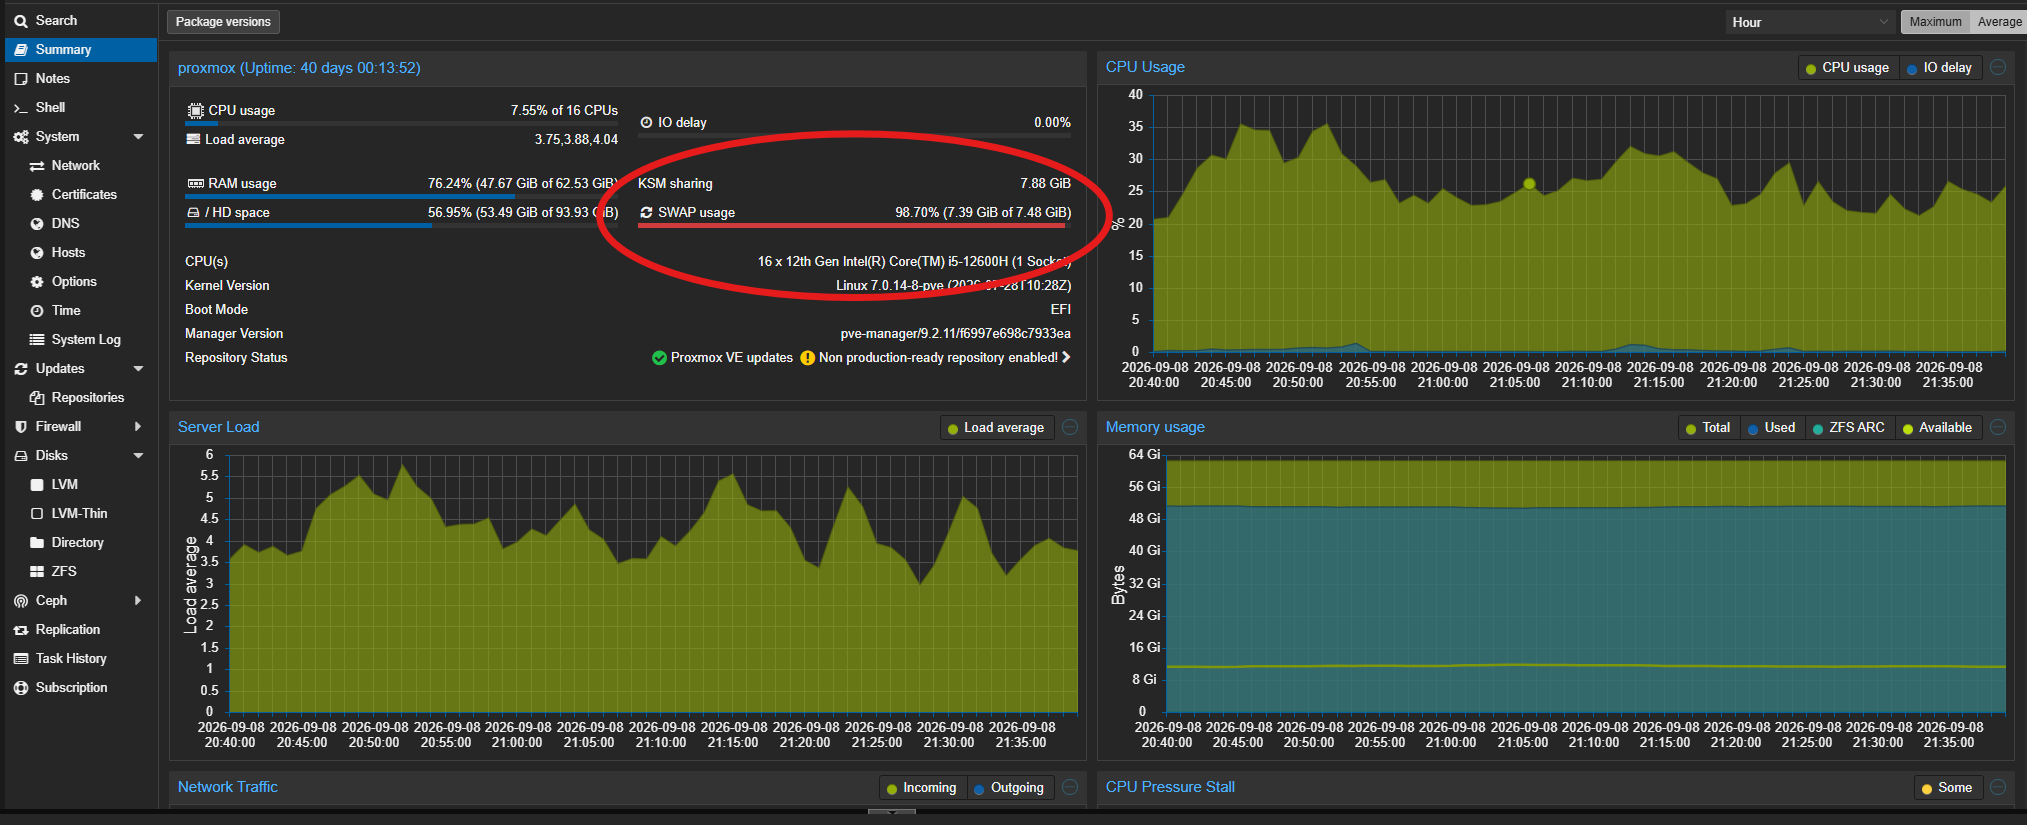
If swap is almost empty but memory still looks full, your guests are not the cause. Go to the ZFS step near the end instead.
Add up what you have actually promised
The web interface shows each guest on its own, so you cannot see the total there. Ask the host for it:
{ for id in $(qm list | awk "NR>1 {print \$1}"); do qm config $id; done; \
  for id in $(pct list | awk "NR>1 {print \$1}"); do pct config $id; done; } \
| awk "/^memory:/ {sum += \$2} END {printf \"assigned to guests: %.1f GiB\n\", sum/1024}"assigned to guests: 123.0 GiBCompare that with what the host has:
awk "/MemTotal/ {printf \"installed: %.1f GiB\n\", \$2/1048576}" /proc/meminfoGiving out more memory than you have is not always wrong. Ballooning is made for this, and guests rarely use everything they get. But at twice the real memory it stops working well, and the host starts to use the disk instead.
Find the guests that do not need what they were given
Do not trust the assigned number. Ask each guest how much it really uses.
If the QEMU guest agent is installed, Proxmox can show what the guest sees:
qm agent 100 ping && qm config 100 | grep -E "^(memory|balloon|agent):"In a Windows guest, look at Committed. You find it in Task Manager under Performance, then Memory. Or use PowerShell:
Get-Counter "\Memory\Committed Bytes" | Select-Object -ExpandProperty CounterSamples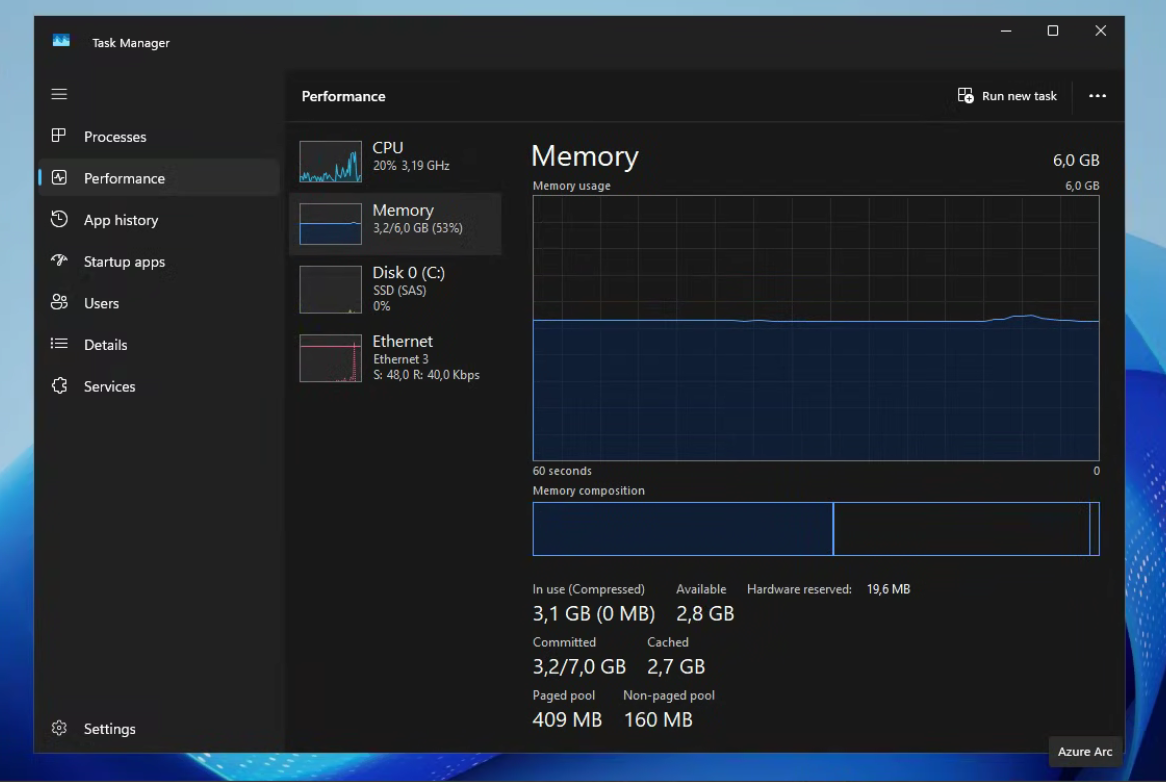
In a Linux guest:
free -hThis is usually where you find the problem. A domain controller on my host had 16 GiB assigned, but it used only 4.4 GiB. Its directory database was 40 MB, and LSASS, the process most people think is huge, used 157 MB. It had four times more memory than it ever needed, only because 16 looked like a safe number when the VM was created.
Check every guest before you change any of them. The biggest surprises are often the guests you did not suspect.
Give the memory back
A memory change works only after the VM starts again, so plan a time to restart it.
qm set 100 --memory 6144Some servers must never lose memory while they run, for example a domain controller or a database. Fix their memory as well:
qm set 100 --balloon 0balloon 0 does not mean no memory. It means no ballooning: the guest always gets exactly what you assigned, and the host never takes it back. Use it where a short freeze would be worse than a little wasted memory. Leave ballooning on for all other guests, because that is what makes sharing memory work.
For containers, the change works right away. No restart is needed:
pct set 100 --memory 6144Stop the lab guests from starting at boot
Many guests in a homelab are made for one afternoon of testing, but then start every time the host boots. They use memory even when nobody uses them.
qm set 100 --onboot 0Then shut down the ones you do not use now:
qm shutdown 100Five test machines with 4 GiB each use 20 GiB. On my host, that alone was a third of the problem. The machines are still there and you can still start them. They just do not use memory while you do not need them.
Turn KSM back on
KSM (Kernel Same-page Merging) finds memory that is the same in several VMs and keeps only one copy. If several guests run the same operating system, this often saves several GiB, with no setup.
systemctl status ksmtunedIf it is not running:
systemctl enable --now ksmtunedWait a few minutes, then see what it found:
cat /sys/kernel/mm/ksm/pages_sharing1043201Multiply this number by 4096 to get bytes. Here it is about 4 GiB of memory that KSM now keeps only once.
Two things to know. KSM works only for virtual machines, not for LXC containers, because containers share the host kernel. Also, researchers have shown that shared memory can leak information between guests. If your guests belong to different people who must not see each other's data, leave KSM off. In a homelab where every guest is yours, KSM costs you almost nothing.
Drain the swap
When memory is really free again, the data already in swap stays on the disk and stays slow. This command moves it back into RAM:
swapoff -a && swapon -aRead the warning before you run it. swapoff must move everything in swap back into RAM. If there is less free memory than used swap, the system kills programs to make room, and it does not care which ones are important. Check first:
free -hUsed swap must be clearly smaller than available memory. If it is not, shut down one more guest and check again.
If memory is full but swap is empty, look at ZFS
On a Proxmox host installed on ZFS, the ARC read cache uses part of the RAM, and that memory shows as used. The system can give it back when needed, so it is rarely the real problem. But check it before you shrink guests that are not the cause.
cat /sys/module/zfs/parameters/zfs_arc_maxZero means the default. The default has changed between Proxmox versions, so check what your version does. If the host also works as storage, leave the ARC as it is, because the cache is doing useful work. A host installed on LVM-thin, like the one in this guide, has no ARC, so you can skip this step.
Verify
free -h total used free shared buff/cache available
Mem: 62Gi 31Gi 27Gi 118Mi 4.1Gi 29Gi
Swap: 8.0Gi 0B 8.0GiSwap is empty, available memory is back to tens of GiB, and the web interface is fast again. No new hardware and no reinstall.
What to keep doing
Each time you add a guest, compare the total assigned memory with the installed memory. It is one command, and it is the number that warns you before this problem comes back:
{ for id in $(qm list | awk "NR>1 {print \$1}"); do qm config $id; done; \
  for id in $(pct list | awk "NR>1 {print \$1}"); do pct config $id; done; } \
| awk "/^memory:/ {sum += \$2} END {printf \"assigned: %.1f GiB\n\", sum/1024}"
Give each guest what it really uses plus a little extra, not a round number that looks safe. When you finish with a test machine, set onboot 0 the same day, while you still remember what it was for.
Did this guide work for you?
Thank you! That helps me keep this guide right.