Install Immich on TrueNAS with GPU acceleration, and migrate a library without losing faces or albums
Photos on large HDDs, the database on fast NVMe, a working Intel GPU, and a move that keeps all faces and albums.
Before you start
- TrueNAS SCALE with an NVMe pool and an HDD pool
- Docker available on the host
- An Intel iGPU if you want machine learning acceleration
- For a migration: access to the old system, and enough space for the library on the new one
Your values
Fill these in and every command below updates to match. Nothing is sent anywhere.
Run this at your own risk. These steps worked on my hardware; yours may differ. Take a backup first, read each command before running it, and see the disclaimer.
Immich is four containers, not one, and they need very different storage. If you get this right at the start, everything later is easier, including the migration. The migration is the part most people get wrong.
The most important lesson, in short: your photos are not the valuable part. Every face you named, every album, every person and every place is in the Postgres database. If you copy only the photos to a new server and let Immich import them again, you keep the pictures but lose everything you did with them.
What the four parts are, and what each one needs
| Container | What it does | Where it belongs |
|---|---|---|
immich_server |
Web interface, uploads, the API | Library on bulk storage |
immich_postgres |
Faces, albums, people, search vectors | Fast storage. This is the most valuable part. |
immich_machine_learning |
Face detection, smart search, OCR | Model cache on fast storage |
immich_redis |
Job queue and cache | Nothing to persist |
The database does much more random reading and writing than a media server's database. Every smart search and every face match uses a vector index, so on hard disks the whole interface feels slow. Redis is a cache and has no volume on purpose. If it is lost, the jobs are simply added to the queue again.
Plan the storage
zfs create -p nvme/databases/immich
zfs create -p nvme/apps/immich/model-cache
zfs create -p tank/Immich
Three datasets, three jobs:
/mnt/nvme/databases/immich- the Postgres data directory/mnt/nvme/apps/immich/model-cache- the downloaded ML models, a few GB, read often during scanning/mnt/tank/Immich- the photo library, thumbnails and converted videos
A separate dataset for the database helps with more than speed. You can snapshot it on its own schedule. A database snapshot is small and quick, a library snapshot is neither.
Configure it
You configure Immich with a .env file next to the compose file. The paths are the important part.
mkdir -p /mnt/nvme/apps/immich
cd /mnt/nvme/apps/immich
cat > .env <<'EOF'
# Where the photo library lives - bulk storage
UPLOAD_LOCATION=/mnt/tank/Immich

# Where the Postgres data directory lives - fast storage
DB_DATA_LOCATION=/mnt/nvme/databases/immich

# Pin the version. Never run :release in production and wonder why it changed.
IMMICH_VERSION=v3.1.0

TZ=Etc/UTC

DB_PASSWORD=CHANGEME
DB_USERNAME=postgres
DB_DATABASE_NAME=immich
EOF
Change DB_PASSWORD before you start anything. It is only used between the containers, but it is written into the database at the first start. Changing it later is much more work than choosing it now.
Enable GPU acceleration properly
Machine learning on the CPU works, but it is slow. On a large library, face detection and smart search take days instead of hours. An Intel iGPU with OpenVINO fixes that.
You need two things, and both must be true. People lose time here, because when only one is right, it looks exactly like both are right, until you check.
First, the machine learning image must be the OpenVINO version. Look at the end of the name:
ghcr.io/immich-app/immich-machine-learning:v3.1.0-openvinoSecond, the container must really be able to reach the GPU. Immich includes a hwaccel.ml.yml file for this. Its openvino section passes the render device into the container and sets the cgroup rule that allows it:
cd /mnt/nvme/apps/immich
grep -A 8 'openvino:' hwaccel.ml.ymlopenvino:
device_cgroup_rules:
- 'c 189:* rmw'
devices:
- /dev/dri:/dev/dri
volumes:
- /dev/bus/usb:/dev/bus/usbIn your docker-compose.yml, the machine learning service extends that section:
immich-machine-learning:
  extends:
    file: hwaccel.ml.yml
    service: openvino
Verify the GPU is actually reachable
Do not skip this. A missing device does not show an error. Immich just uses the CPU instead, and everything keeps working, only slowly, forever.
docker exec immich_machine_learning ls -l /dev/dricrw-rw---- 1 root video 226, 0 card0
crw-rw---- 1 root 107 226, 128 renderD128If it says "No such file or directory", the GPU is not passed through, and no other setting will help.
Verify OpenVINO is actually being used
The device must be there, but that alone is not enough. Check the logs:
docker logs immich_machine_learning 2>&1 | grep -i -E 'openvino|provider' | tail -5INFO Setting execution providers to ['OpenVINOExecutionProvider',
'CPUExecutionProvider'], in descending order of priorityYou want OpenVINOExecutionProvider first in the list. CPUExecutionProvider after it is the fallback, and that is correct, it should be there. If CPU is the only entry, OpenVINO could not start.
The second GPU mapping, and why the first one proves nothing
Everything above is for machine learning. Video transcoding is a different container with its own device mapping. If the first one works, that tells you nothing about the second.
It solves the problem of phone videos. A 4K video from a new phone is HEVC, often 10-bit, and browsers cannot play it. By default Immich sends the original, so the thumbnail appears but the video does not play, and no error is shown. The solution is Immich's own Transcode Videos job. It writes an H.264 copy next to the original and sends that copy to any device that cannot play the original. Your files are never changed.
That job runs ffmpeg, and ffmpeg runs in immich_server, not in immich_machine_learning. So the /dev/dri check earlier, the one that worked, checked the wrong container:
docker exec immich_server ls -l /dev/drils: cannot access '/dev/dri': No such file or directoryIn my case, machine learning had the device and OpenVINO worked perfectly. Face detection ran on the GPU, but every video was converted on the CPU. Nothing showed this. The only sign was that a few thousand videos would take days, and the fans never stopped.
The two files are different. hwaccel.ml.yml is for machine learning. hwaccel.transcoding.yml is for video. They come together, but they are used by different services.
Check the service name before you use it
The documentation says qsv. The file you get may say quicksync. Read your own file instead of trusting either one:
grep -n -E '^[[:space:]]{0,2}[a-z-]+:' /mnt/nvme/apps/immich/hwaccel.transcoding.yml9:services:
10: cpu: {}
12: nvenc:
24: quicksync:
28: rkmpp:
44: vaapi:
48: vaapi-wsl:Wire it up without touching the compose file
Add an override file instead of editing docker-compose.yaml. Compose reads docker-compose.override.yaml automatically. With the change in its own file, an Immich upgrade that replaces the compose file cannot undo it without you noticing. Use the service name that your own file printed above.
services:
  immich-server:
    extends:
      file: hwaccel.transcoding.yml
      service: quicksync
Check the combined configuration before you apply it. This command builds the configuration and prints it without changing anything:
cd /mnt/nvme/apps/immich
docker compose config | grep -B2 -A6 'dev/dri'
Keep the grep filter, and do not paste the output anywhere. docker compose config fills in every variable, so without the filter it prints your database password in the terminal. That is the quickest way for a password to end up in a screenshot or a forum post.
You want to see /dev/dri under immich-server. Then restart only that one container. Postgres, Redis and machine learning are not touched, and the library and database are not affected at all:
cd /mnt/nvme/apps/immich
docker compose up -d immich-server
docker exec immich_server ls -l /dev/dricrw-rw---- 1 root video 226, 0 card0
crw-rw---- 1 root 107 226, 128 renderD128If the container does not run as root, its group list must also include the group that owns renderD128 (107 above). Check with docker exec immich_server id. If the process cannot open the device, it fails exactly as if there were no device.
Then the setting, which is the other half
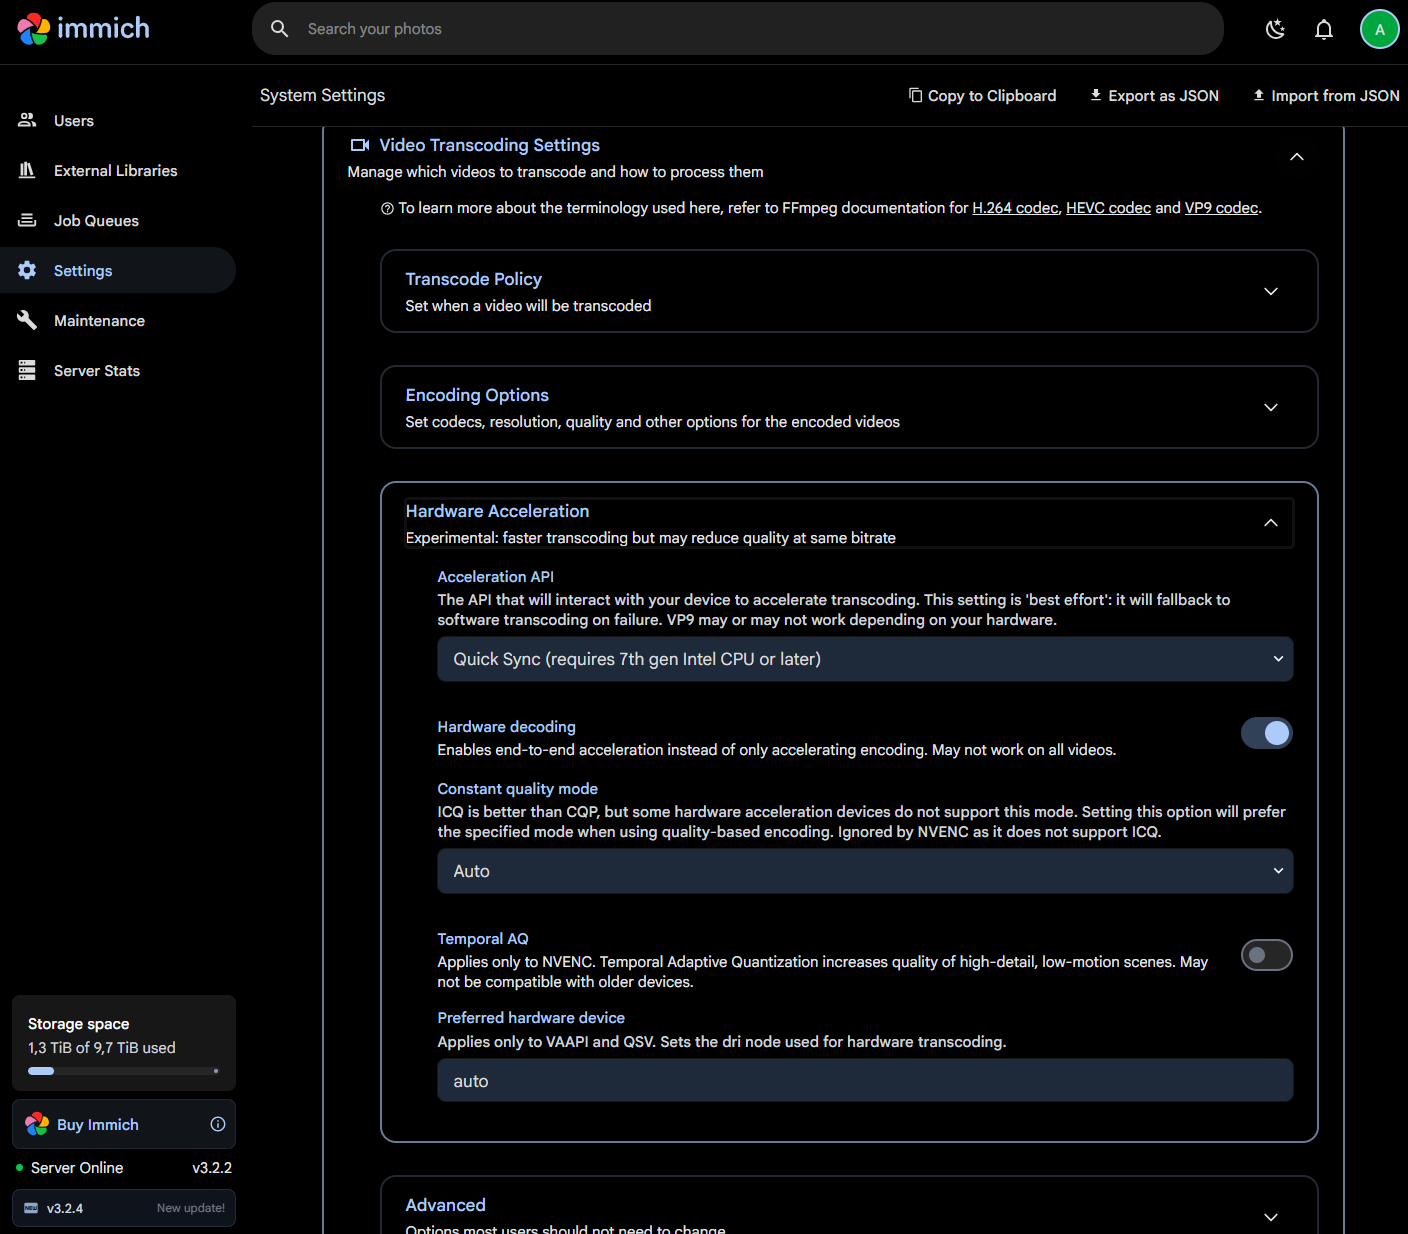
In Administration -> Settings -> Video Transcoding -> Hardware Acceleration, set the Acceleration API to Quick Sync and turn on Hardware decoding.
Neither part works alone. The device without the setting does nothing. The setting without the device falls back to software. Immich describes the API setting as "best effort: it will fallback to software transcoding on failure". That is exactly why this is hard to notice: when it fails, it still works, just slowly.
Prove it is actually on the GPU
Run this on the host, not in the container, while a video is being converted:
ps -eo args | grep -i ffmpeg | grep -v grep | head -3/usr/bin/ffmpeg -hwaccel qsv -hwaccel_output_format qsv -async_depth 4 \
-qsv_device /dev/dri/renderD128 -threads 1 -i ... -c:v h264_qsv -c:a aac ...Look for three things. -c:v h264_qsv is the encoder on the GPU. -hwaccel qsv is the decoder on the GPU. And -hwaccel_output_format qsv is the best one: it keeps the frames in GPU memory between the two steps, instead of copying them to system memory and back. That is what the Hardware decoding switch gives you. If you see libx264 anywhere in that line, it is still software, no matter what the settings page says.
cat /sys/class/drm/card0/gt_act_freq_mhzA number in the hundreds or low thousands during a transcode means the GPU is working. Zero all the time means it is not being used.
The quality trade, stated honestly
Immich's own warning on that settings page says "faster transcoding but may reduce quality at same bitrate", and that is true. With similar settings, hardware encoders make larger files with lower quality than software encoders.
So if you switch in the middle of a large batch, the videos already converted on the CPU are the better ones. Leave them. Converting the whole library again on the GPU, just so all videos are the same, would make those worse, not better.
Running a few thousand of them
This is a long job, so plan it like one.
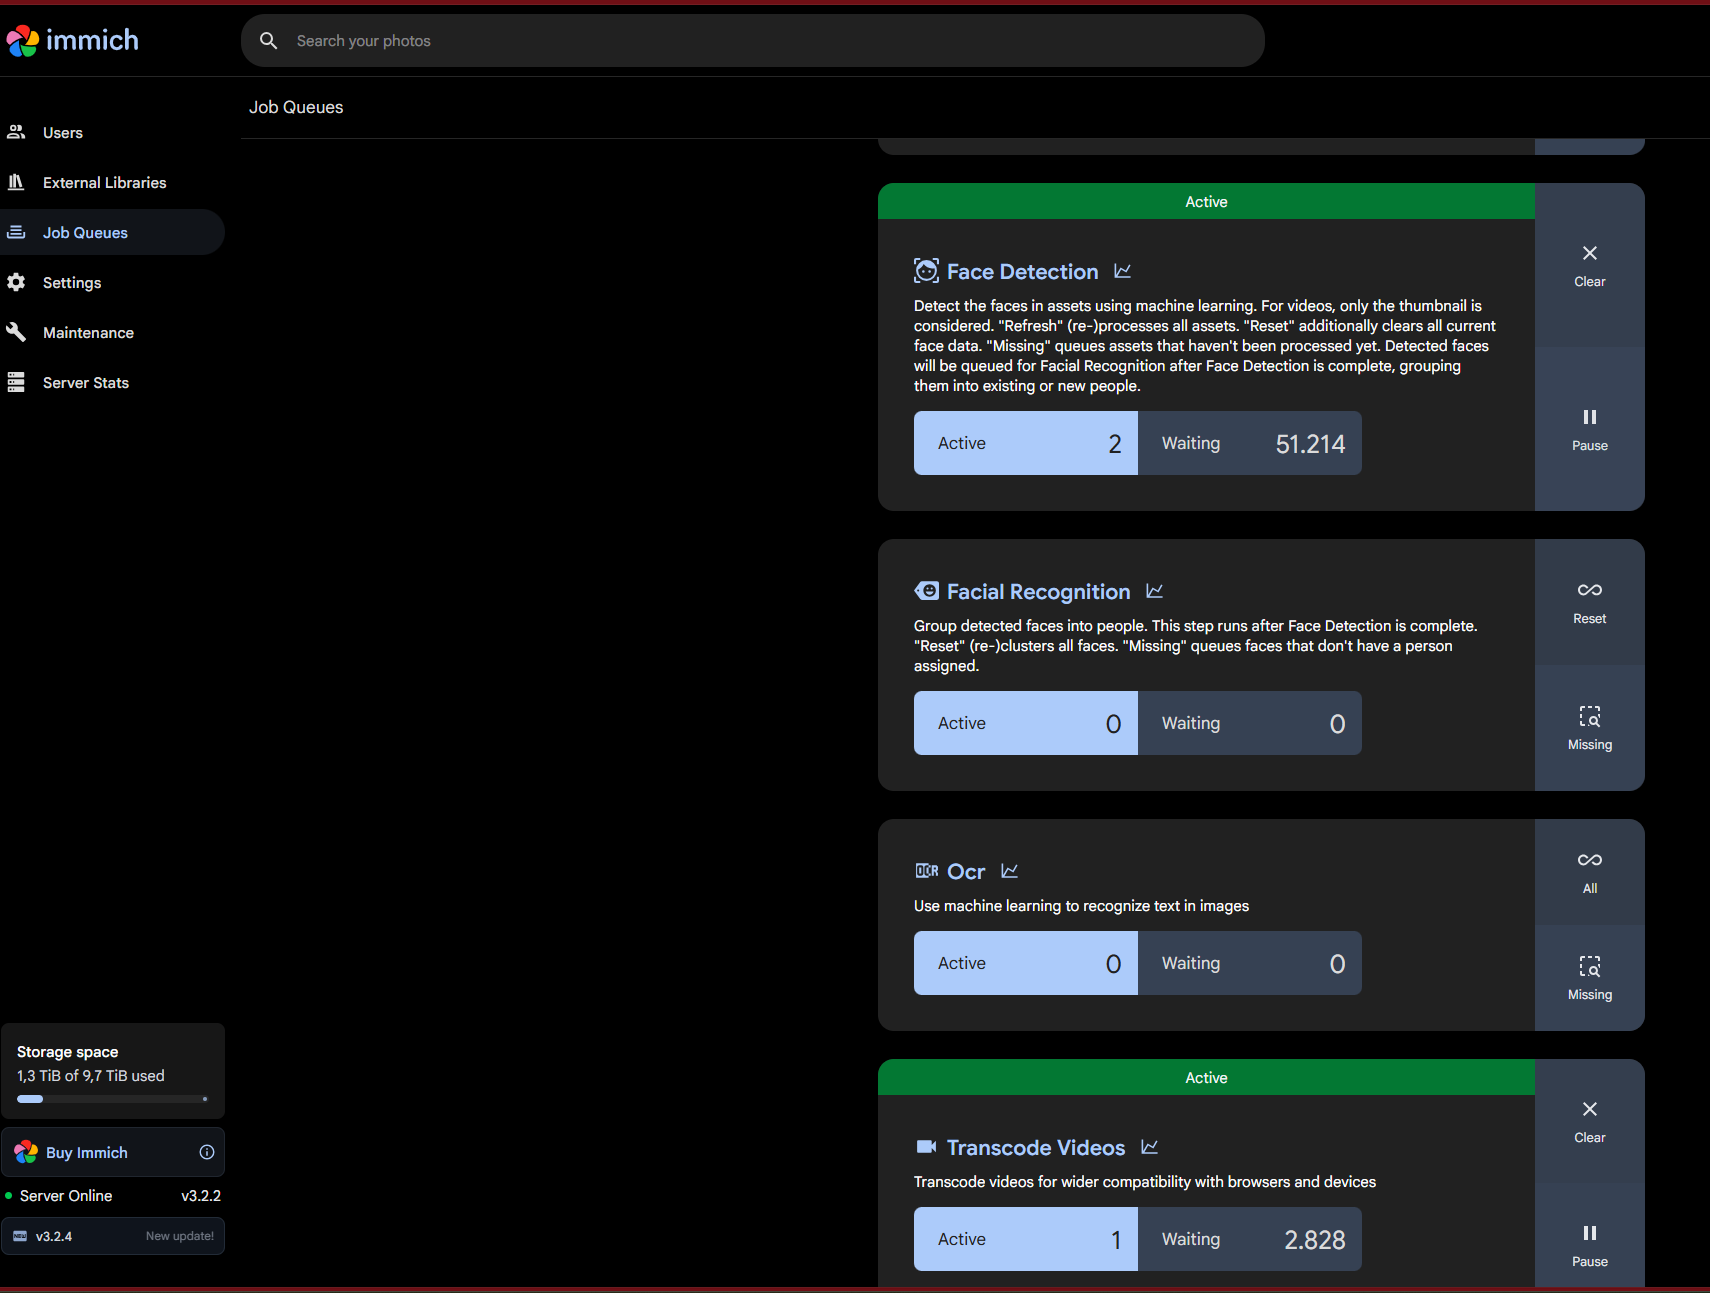
Immich shows the queue under Administration -> Job Queues, with Active and Waiting counts and a Pause button on each. Pausing keeps the finished work. It does not start again from the beginning.
Concurrency is on the same page. One integrated GPU is one encoder. If you raise the transcode concurrency, several jobs share the same GPU, but they do not finish sooner. Leave it low, unless you have measured that more helps.
And a NAS in a flat is not a NAS in a basement. Converting a few thousand files means hours of disk and fan noise. That is fine in the afternoon, but not at eleven at night. Pause the queue in the evening and continue in the morning. It only takes a few more days, and time is the cheapest thing here. Think about this before you start, not at bedtime.
Migrating an existing library
Read this part twice.
What is stored where. The image files are on disk. Everything else is in Postgres: the people you named, the albums you made, the face groups, the smart search data, the shared links, and the users. If you move only the photos, Immich imports them again and runs face detection from the start, without any of your names.
So the database is the real migration. The photos are just files that come with it.
Option one: restore a database dump. This is the safer way. Choose it if the two systems differ in any way.
Immich makes its own dump every night. Find it on the old system:
ls -la /mnt/tank/Immich/backups/immich-db-backup-20260913T020000-v3.1.0-pg14.19.sql.gzThe file name shows the Immich version and the Postgres version. You need to know both before you restore it somewhere else.
Copy the photo library and that dump to the new machine. Start the new stack, so it creates an empty database. Then stop the server and machine learning containers, keep Postgres running, and restore the dump into it. Immich's documentation has the current restore command for your version. Use theirs and not a copied one, because it changes between versions.
Option two: copy the Postgres data folder. It is faster and needs no restore, but it only works under strict conditions.
It only works if the Postgres major version and the vector extension versions are exactly the same on both sides. Immich does not use normal Postgres. It uses a version with VectorChord and pgvecto.rs built in. If the versions differ, the database does not start at all.
If you choose this option, fix the image by its digest instead of its tag, so both sides always use exactly the same version:
image: ghcr.io/immich-app/postgres:14-vectorchord0.4.3-pgvectors0.2.0@sha256:...Stop Immich completely on both sides before you copy. A Postgres data folder copied while it is running is a broken database.
docker compose down
rsync -aHAX --info=progress2 \
  old-nas.example.lan:/path/to/old/postgres/data/ \
  /mnt/nvme/databases/immich/
For both options: keep the library path the same. Immich stores paths. If UPLOAD_LOCATION pointed somewhere else on the old system, the database looks for files in places where they are not.
External libraries: photos that stay where they are
Immich can read a folder where it is, without importing it. Your photo folders keep their structure, other programs can still write to them, and the photos still appear in Immich with faces and search.
Mount the folder into the server container:
volumes:
  - /mnt/tank/Immich:/data
  - /mnt/tank/Home/Photos:/external
Then, in the web interface, go to Administration, External Libraries, and add /external. This is the path inside the container, not the host path.
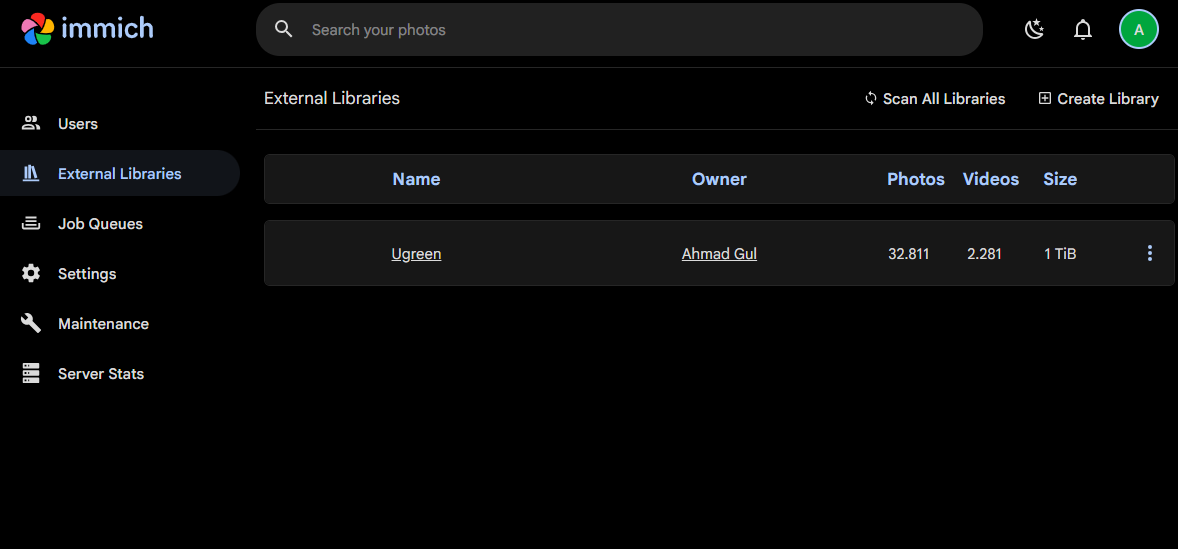
Two things to know about external libraries. Immich does not move, rename or delete those files, and that is the point. And if a file disappears from the folder, Immich marks it as offline but keeps your metadata. So a disk that is unmounted for a while does not destroy your albums.
Immich backs up its own database. Check where.
Immich makes a database dump on a schedule and writes it into the library folder:
ls -la /mnt/tank/Immich/backups/ | tail -5This is really useful, and many people do not know about it.
But it has one clear problem if you do nothing else. The dumps are on the same pool as the photos. If you lose the pool, you lose the photos and also the only thing that could restore their metadata, at the same time.
Snapshots are not backups. A daily snapshot of the library dataset includes those dumps, and it protects you from deleting something by mistake or from a bad upgrade. It does not protect you from losing the pool, because it is stored on the pool. What you need is the snapshots copied to a second machine:
zfs list -o name | grep -i immichRun that on the backup machine. If the Immich datasets appear there, the photos and the dumps are both safe on another machine.
If you copy both the library and the live database folder, know the difference. A copied Postgres data folder is like the state after a crash at the time of the snapshot. It can usually be restored, but a database saved in the middle of a write may not be clean. The nightly SQL dump is a proper, clean export.
In a real recovery, use the dump first. Try the copied data folder second, as the fast option. Having both is right. Thinking they are the same is not.
After it is running
Check these in order:
docker exec immich_machine_learning ls -l /dev/dri- device present- The logs show
OpenVINOExecutionProviderfirst - Start a smart search job and watch the iGPU clock go up:
cat /sys/class/drm/card0/gt_act_freq_mhz - Search for a person by name. If they are there, your migration kept the database, and you kept everything that mattered.
Did this guide work for you?
Thank you! That helps me keep this guide right.