Jellyfin on TrueNAS with media on HDD and everything else on NVMe
Install Jellyfin on TrueNAS with media on large HDDs and the database on fast NVMe, so the app stays fast.
Before you start
- TrueNAS SCALE with two pools: an NVMe pool and an HDD pool
- Docker available on the host
- Shell access with permission to create datasets
- Your media already on the HDD pool, or ready to copy there
Your values
Fill these in and every command below updates to match. Nothing is sent anywhere.
Run this at your own risk. These steps worked on my hardware; yours may differ. Take a backup first, read each command before running it, and see the disclaimer.
Jellyfin needs two very different kinds of storage, and most setups ignore the difference.
The media files are large, written once, and read from start to end. They belong on hard disks (HDDs), where space is cheap.
The config folder, the metadata database, the image cache and the transcode space are small. But they get many small random reads and writes every time someone browses the library or starts a video. On the same hard disks, these small operations wait behind the big ones, and the interface feels slow. You never see the reason in a bandwidth graph.
This guide builds Jellyfin with these two kinds of work on separate pools: the media on a RAIDZ HDD pool, and everything else Jellyfin uses on NVMe.
It also explains why you should start with a fresh config folder instead of copying one from an old install. That decision saves you a whole weekend of problems.
Plan the layout before creating anything
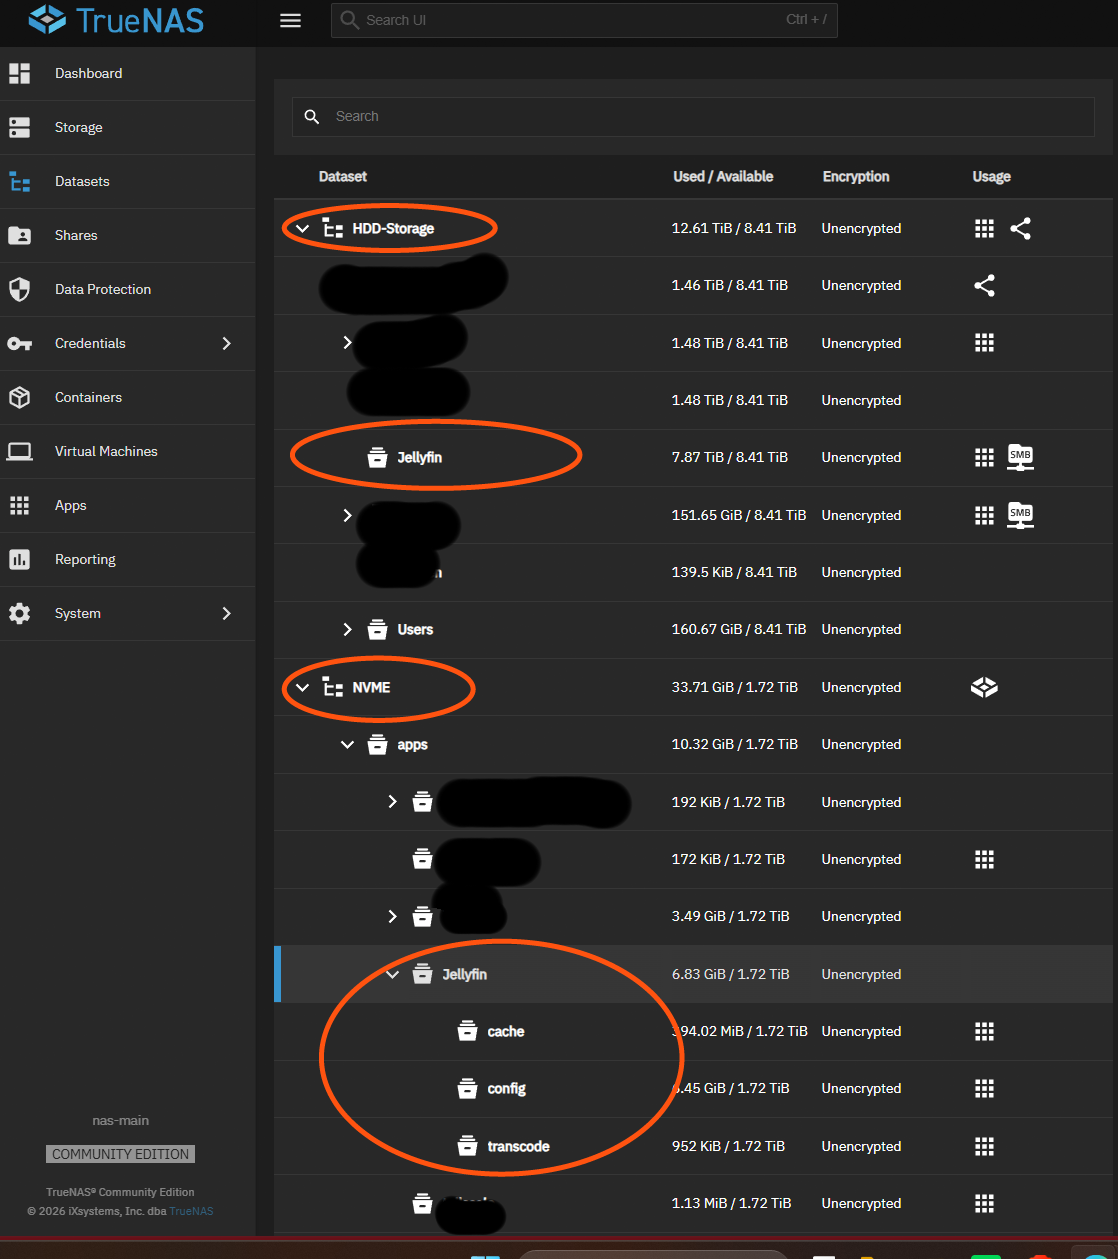
Use four separate datasets, not one. Then you can snapshot, copy and delete each one on its own. Deleting the cache is something you will do from time to time, without touching anything else.
| Dataset | Pool | Holds |
|---|---|---|
nvme/apps/jellyfin/config |
NVMe | Database, settings, users, library definitions |
nvme/apps/jellyfin/cache |
NVMe | Images, chapter thumbnails, transient metadata |
nvme/apps/jellyfin/transcode |
NVMe | Scratch space while transcoding |
tank/media |
HDD | The media itself |
The transcode folder belongs on NVMe. Transcoding writes small pieces of video during the whole stream. On the media disks, every playback would slow itself down.
A separate transcode dataset does nothing on its own. Jellyfin writes transcode files into its cache folder, unless you set Transcode path in the transcoding settings. If you mount a transcode dataset and forget that step, it stays empty while transcodes go to the cache.
So is the fourth dataset worth it? Not for speed. The cache is already on NVMe, so transcodes are on NVMe either way. During playback you will not notice any difference.
It is useful for three practical reasons, but only if one of them applies to you:
- A quota. A stuck transcode, or several at once, can write a lot of temporary data. A dataset with a quota cannot fill the pool that also holds your app config.
- Snapshots. If you snapshot the cache dataset, the snapshots also keep the temporary transcode files, and they keep using space long after the files are deleted. A separate dataset can just be left out of the snapshot schedule.
- Clearing one without the other. You can empty the transcode space without clearing the image cache.
If you do not snapshot these datasets and your NVMe pool has enough space, just leave Transcode path empty. That is one less thing that can go wrong. If you do add it, set the path as described below. Then play something that really transcodes, and check that files appear there. If the transcode path points to a mount that does not exist, or that the container user cannot write to, playback breaks. Jellyfin does not fall back to another folder.
Create the datasets
zfs create -p nvme/apps/jellyfin/config
zfs create -p nvme/apps/jellyfin/cache
zfs create -p nvme/apps/jellyfin/transcode
zfs create -p tank/media
Then the media libraries, one dataset each, so you can snapshot and share them separately:
zfs create tank/media/movies
zfs create tank/media/tv
zfs create tank/media/kids
zfs create tank/media/music-videos
Use zfs create, and later zfs rename, for datasets. Do not use mv to reorganise them. mv copies the contents to another filesystem instead of renaming the dataset. For a large library that means copying terabytes, while a rename takes one second.
Decide now: fresh config, not a migrated one
If you come from an old Jellyfin install, this is the important decision. It is tempting to copy the old config folder, so you keep the watch history and users.
But here is what you really copy along with it.
Jellyfin stores the full internal path of every library. Not the file names, but the paths as the old container saw them. If the old container mounted the media at a different path, or with different capital letters or spaces, every library finds nothing. For the database, /Media/TV Shows and /media/tv are two completely different places.
It also stores libraries by GUID (a unique ID). If a library was ever deleted and created again, it has a new GUID. Anything that still uses the old one finds nothing, without any error.
The config folder contains marker files that say a folder is already set up. In a new install, they describe folders that do not exist, and the container can crash at start.
And there are link files that connect collections and playlists to items. Old ones point to items that no longer exist, and they fail without an error.
That is the pattern: almost none of this shows a useful error. You fix one thing, the next one appears, and suddenly it is 2 a.m.
What a fresh config costs you: watch history, user accounts, and any metadata you edited by hand. What it does not cost you: your media, which was never in the database. A fresh install scans and builds the libraries again by itself while you sleep.
If you have already fixed two problems and a third one appears, stop and start fresh. Do not keep going just because you already spent time on it.
Deploy the container
Use a fixed version. With latest, an automatic update can change how Jellyfin works on some random evening, and you will not know why.
mkdir -p /mnt/nvme/apps/jellyfin
cat > /mnt/nvme/apps/jellyfin/compose.yaml <<'EOF'
services:
  jellyfin:
    image: jellyfin/jellyfin:12.0
    container_name: jellyfin
    restart: unless-stopped
    network_mode: host
    user: "1000:1000"
    environment:
      - TZ=Etc/UTC
      - JELLYFIN_CACHE_DIR=/cache
    volumes:
      - /mnt/nvme/apps/jellyfin/config:/config
      - /mnt/nvme/apps/jellyfin/cache:/cache
      - /mnt/nvme/apps/jellyfin/transcode:/transcode
      - /mnt/tank/media:/media:ro
EOF
Two choices are important to understand.
network_mode: host makes DLNA and automatic discovery by clients work. Without it, Jellyfin still works over HTTP, but clients no longer find it by themselves.
The media mount is read-only. Jellyfin does not need to write to your media. A media server with write access to the library could delete files because of a single bug. If you later want Jellyfin to write .nfo metadata next to your files, change it then, on purpose, not now.
Start it
cd /mnt/nvme/apps/jellyfin
docker compose up -d
docker compose logs -f[INF] Jellyfin version: 10.11.11
[INF] Application directory: /config
[INF] Cache directory: /cache
[INF] Startup complete 0:00:06.83When you see that the startup is complete, stop the log view with Ctrl+C. The container keeps running.
Add the libraries, carefully
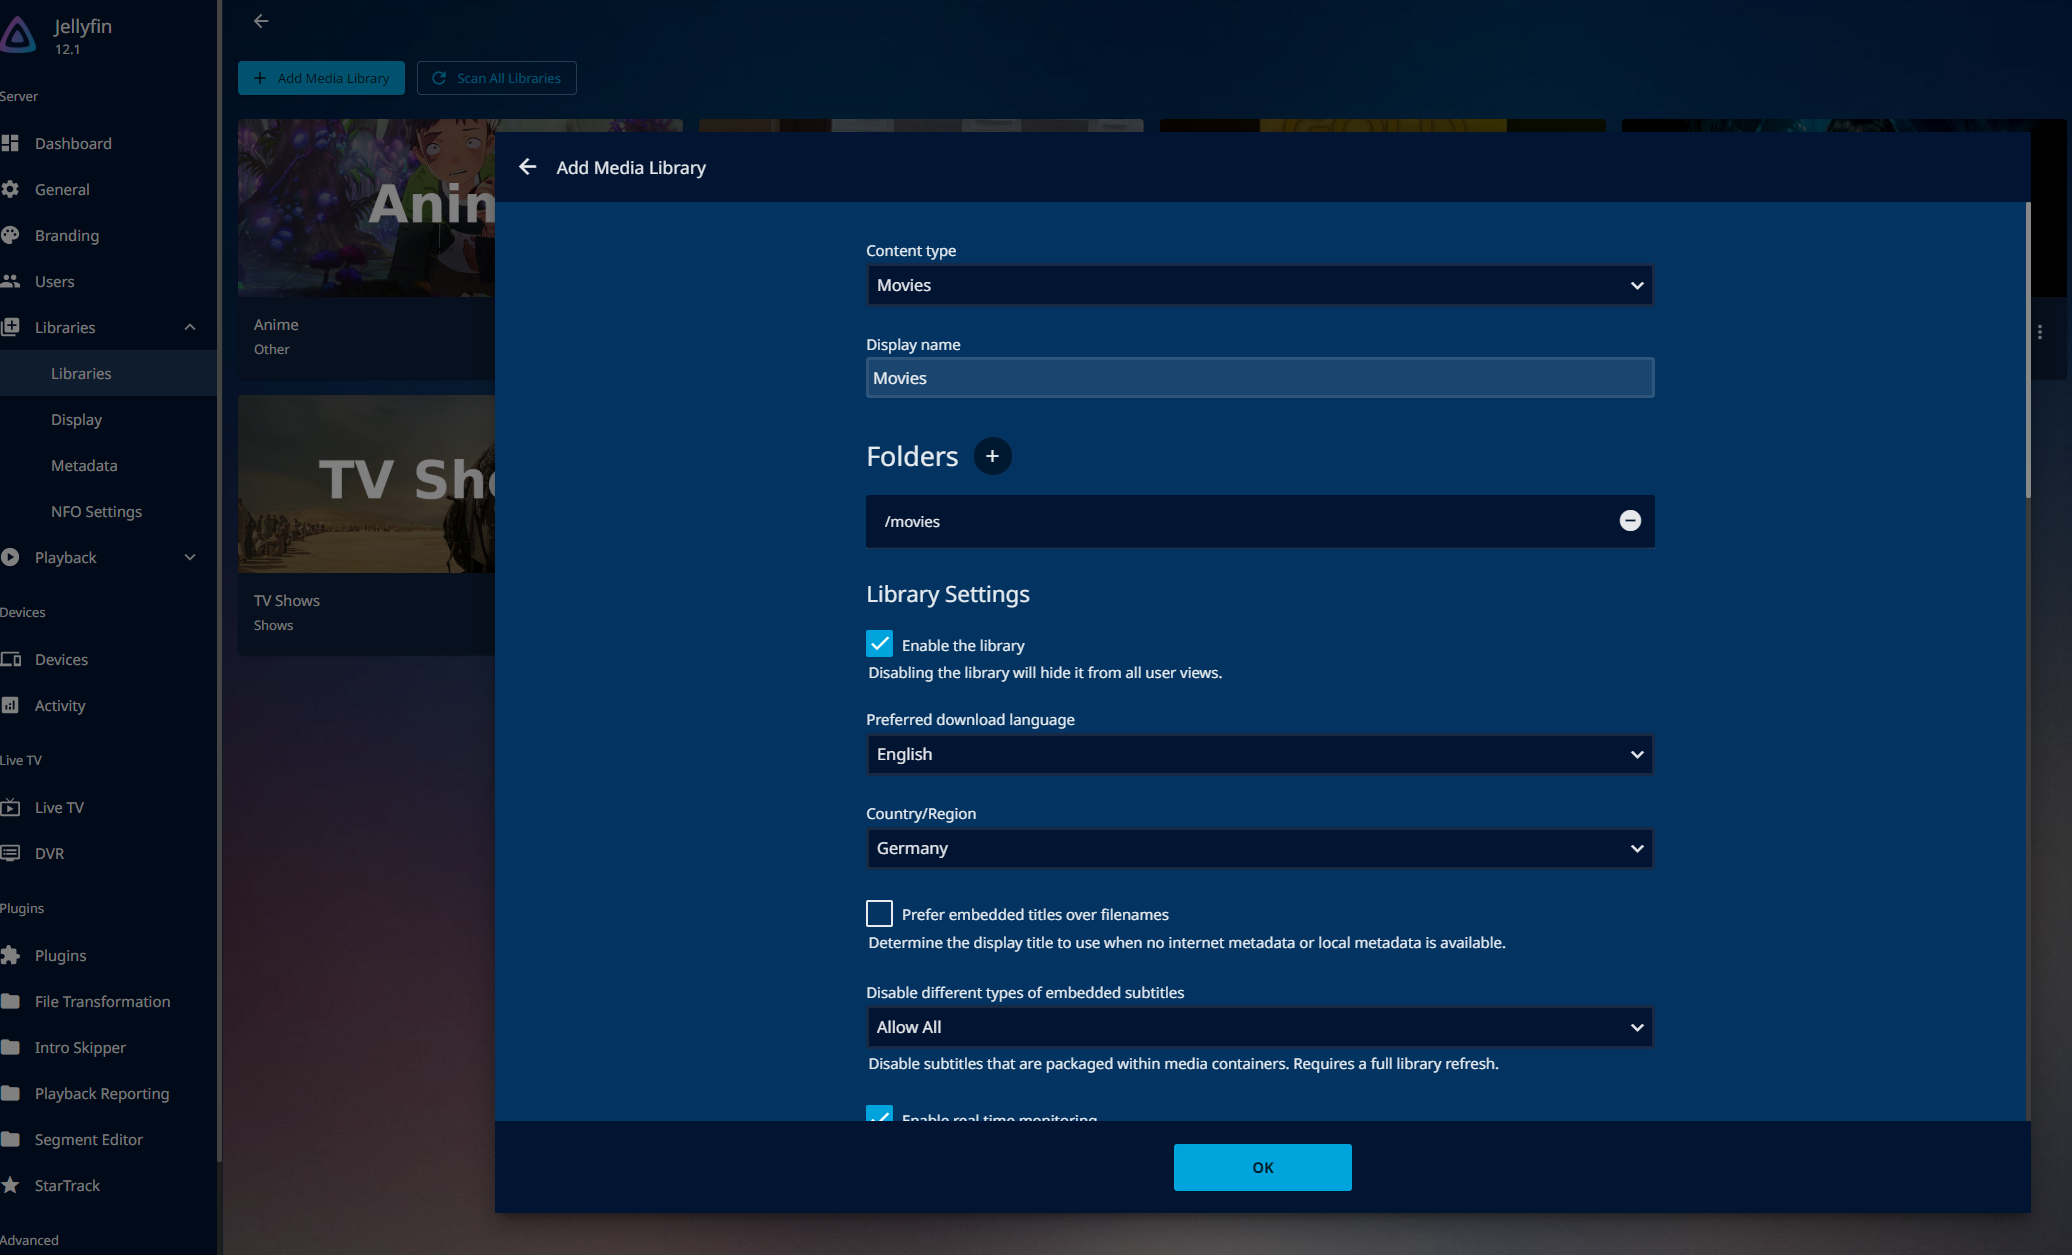
In the setup wizard, add each library with the path inside the container, for example /media/movies, not the host path.
Write down exactly what you enter. The database keeps these paths forever. If they do not match after a later change, the libraries are empty. This is the most common cause. If you ever move the data, change the mount so the container path stays the same. Do not edit the library.
For the same reason, choose your internal paths once and keep them. /media/tv today and /media/TV Shows next year are two different libraries.
Verify
docker exec jellyfin ls -la /mediadrwxr-xr-x 2 1000 1000 4 Sep 12 21:14 kids
drwxr-xr-x 2 1000 1000 4 Sep 12 21:14 movies
drwxr-xr-x 2 1000 1000 4 Sep 12 21:14 music-videos
drwxr-xr-x 2 1000 1000 4 Sep 12 21:14 tvIf the container cannot see the files, no setting in the web interface will help. Check this before you change anything else.
Check that the config and cache are really on NVMe and not somewhere else:
docker inspect -f '{{{{range .Mounts}}}}{{{{.Destination}}}} <- {{{{.Source}}}}{{{{"\n"}}}}{{{{end}}}}' jellyfinClearing the cache is safe. Clearing the config is not.
It is good to know the difference, because they are next to each other.
The cache can be created again. If images are old or the metadata looks wrong, stop the container and empty the cache dataset. It only costs you a new scan.
The config holds your users, your watch history and your library settings. If you empty it, you start fresh as described above.
docker compose stop jellyfin
rm -rf /mnt/nvme/apps/jellyfin/cache/*
docker compose start jellyfin
Transcoding: check the GPU is reachable before tuning anything
This section is in this order on purpose. I did it the other way round and lost many evenings.
Before you change any transcoding setting, check that the container can see the GPU. Two commands:
docker exec jellyfin ls -l /dev/dri
docker exec jellyfin idcrw-rw---- 1 root video 226, 0 card0
crw-rw---- 1 root 107 226, 128 renderD128
uid=568 gid=568 groups=568,44(video),107Both things must be true. The device files must exist inside the container. And the container's group list must include the group that owns renderD128, which is 107 in the output above. On the host, stat -c '%g %G' /dev/dri/renderD128 shows which group that is.
If /dev/dri does not exist in the container, no setting on the Jellyfin transcoding page can help. If the device exists but the group is missing, ffmpeg cannot open it, and transcodes fail as soon as they start.
Why this hides so well
You can use Jellyfin for months with hardware acceleration selected and think it works, because most playback never uses it:
- A capable client direct plays: the server sends the file unchanged
- A browser usually copies the video and converts only the audio, because the video is fine but the audio codec is not
Neither one uses the GPU. Playback is fast, the server is quiet, and everything looks fine. The GPU is only used when the video really must be converted. If the GPU is not reachable, playback stops with an error at that moment, long after you stopped thinking about the settings.
Watch what is actually happening
Run this on the host while you play something. You do not need to install anything.
while true; do
  line=$(docker top jellyfin 2>/dev/null | grep -i ffmpeg)
  g=$(cat /sys/class/drm/card0/gt_act_freq_mhz 2>/dev/null \
      || cat /sys/class/drm/card0/gt/gt0/rps_act_freq_mhz 2>/dev/null || echo n/a)
  if [ -n "$line" ]; then
    c=$(echo "$line" | grep -oE 'qsv|vaapi|libx264|libx265' | sort -u | tr '\n' ' ')
    echo "$(date +%T)  ffmpeg running  codecs=[$c]  gpu=${g}MHz"
  else
    echo "$(date +%T)  idle or copying          gpu=${g}MHz"
  fi
  sleep 2
done
Working hardware transcoding looks like this:
17:37:15  idle or copying          gpu=0MHz
17:37:17  ffmpeg running  codecs=[qsv vaapi ]  gpu=1100MHz
17:37:46  ffmpeg running  codecs=[qsv vaapi ]  gpu=1100MHz
17:37:50  ffmpeg running  codecs=[qsv vaapi ]  gpu=0MHz
How to read it:
codecs=[qsv vaapi]- the hardware is really in usecodecs=[libx264]- software encoding, no matter what the settings page sayscodecs=[]with ffmpeg running - the video is being copied. Only the audio is converted. The GPU is idle because there is no video work, and this is the fastest result.gpu=0MHzwhileqsvis running - throttling works. The encoder has filled its buffer and paused. Without throttling it would run at full speed until the whole film was converted.
The last two confuse many people. Both look like hardware acceleration failed. But one means it was not needed, and the other means it is pausing on purpose. Watch for a minute before you decide anything. One sample tells you almost nothing.
If you change the quality setting during playback, you switch between these states. This is a good way to see all of them at once. Original quality usually copies. A lower quality usually transcodes.
Read the ffmpeg command line
The most useful command. Run it while something plays:
ps -eo args | grep ffmpeg | grep -v grepWhat to look for:
-codec:v:0 copy- the video is being copied, not transcoded. Only the audio is converted. The GPU is idle because there is nothing to do, and this is the fastest possible result.h264_qsv,hevc_qsv,-hwaccel vaapi- the hardware is doing real worklibx264- software encoding-ac 2- the audio is mixed down to stereo, which browsers require. Use a desktop client if you want surround sound.
Only now, the settings
Hardware acceleration. Select QuickSync for an Intel iGPU, but only after the device check above works.
Enable hardware decoding: tick HEVC and also HEVC 10bit. This mistake is easy to miss. If you only tick the 10-bit box, 8-bit HEVC files (a large part of 4K content) use software decoding, while 10-bit files use hardware. Then some files play well and others badly, and you see no clear pattern.
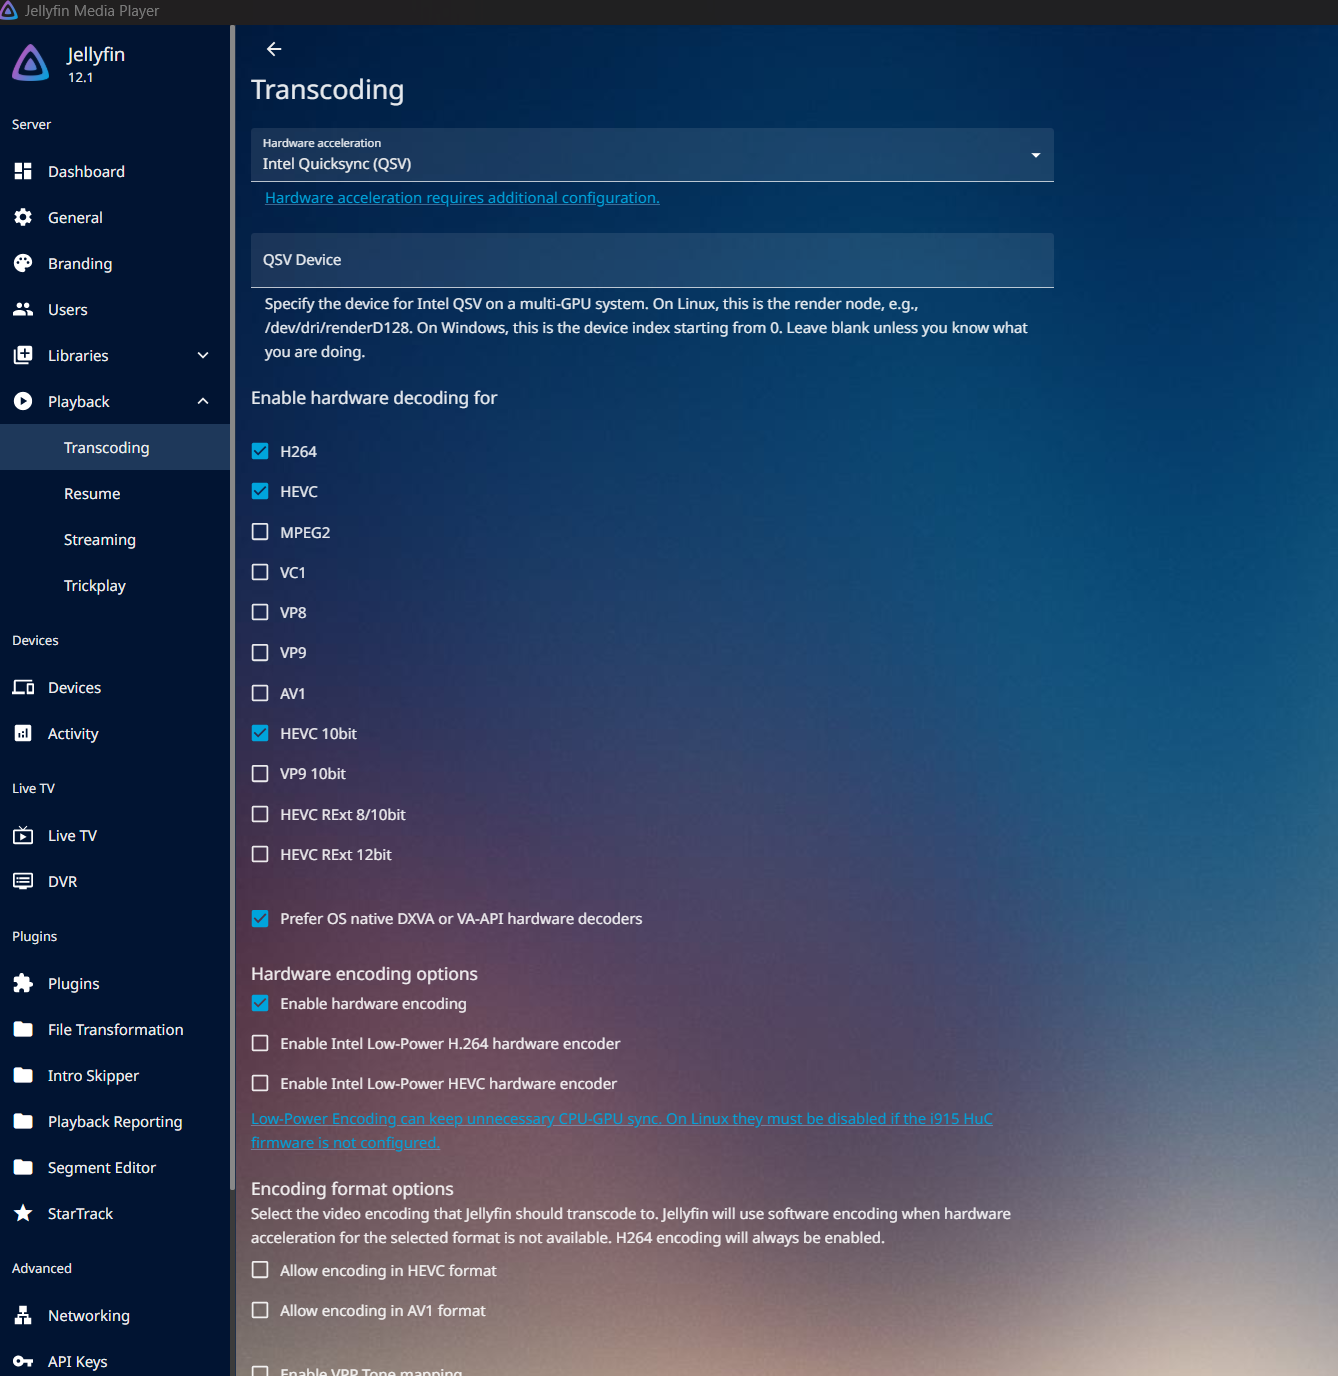
Enable hardware encoding. Leave the Intel Low-Power encoders off, unless you have checked that the i915 HuC firmware is loaded. The interface warns about this, and the warning is real.
Throttle Transcodes: on. Without it, the encoder converts the whole film at full speed as soon as playback starts, and the GPU is fully busy for minutes.
Delete segments: on. Otherwise every segment of a 4K transcode stays on disk until the session ends.
Transcode path. Leave it empty, or set /cache/transcodes. See the section on datasets above.
Encoding format options. Leave Allow encoding in HEVC and AV1 unticked, unless you have a reason. They let Jellyfin transcode into those formats, which needs more power and plays on fewer devices. H.264 is always available and works everywhere.
Tone mapping only matters when HDR content is really being transcoded. Without it, HDR-to-SDR video looks pale, but it still plays. On Intel, try VPP tone mapping first. It uses special hardware and does not need the OpenCL runtime.
The best setting is not on this page. A transcode that never happens is faster than any transcode. If one file always has problems, find out why the client cannot direct play it. Often the reason is the audio track or the container, not the video. Then keep a compatible copy, instead of converting it live every time.
What this layout gives you afterwards
Snapshot the config dataset before every Jellyfin upgrade. Then a bad release means a quick rollback, not starting fresh. You can copy the config without copying terabytes of media. You can delete and recreate the cache whenever it causes problems, without touching anything important. And the transcode work stays off the disks with your media.
None of this is possible if everything is in one folder on one pool.
Did this guide work for you?
Thank you! That helps me keep this guide right.